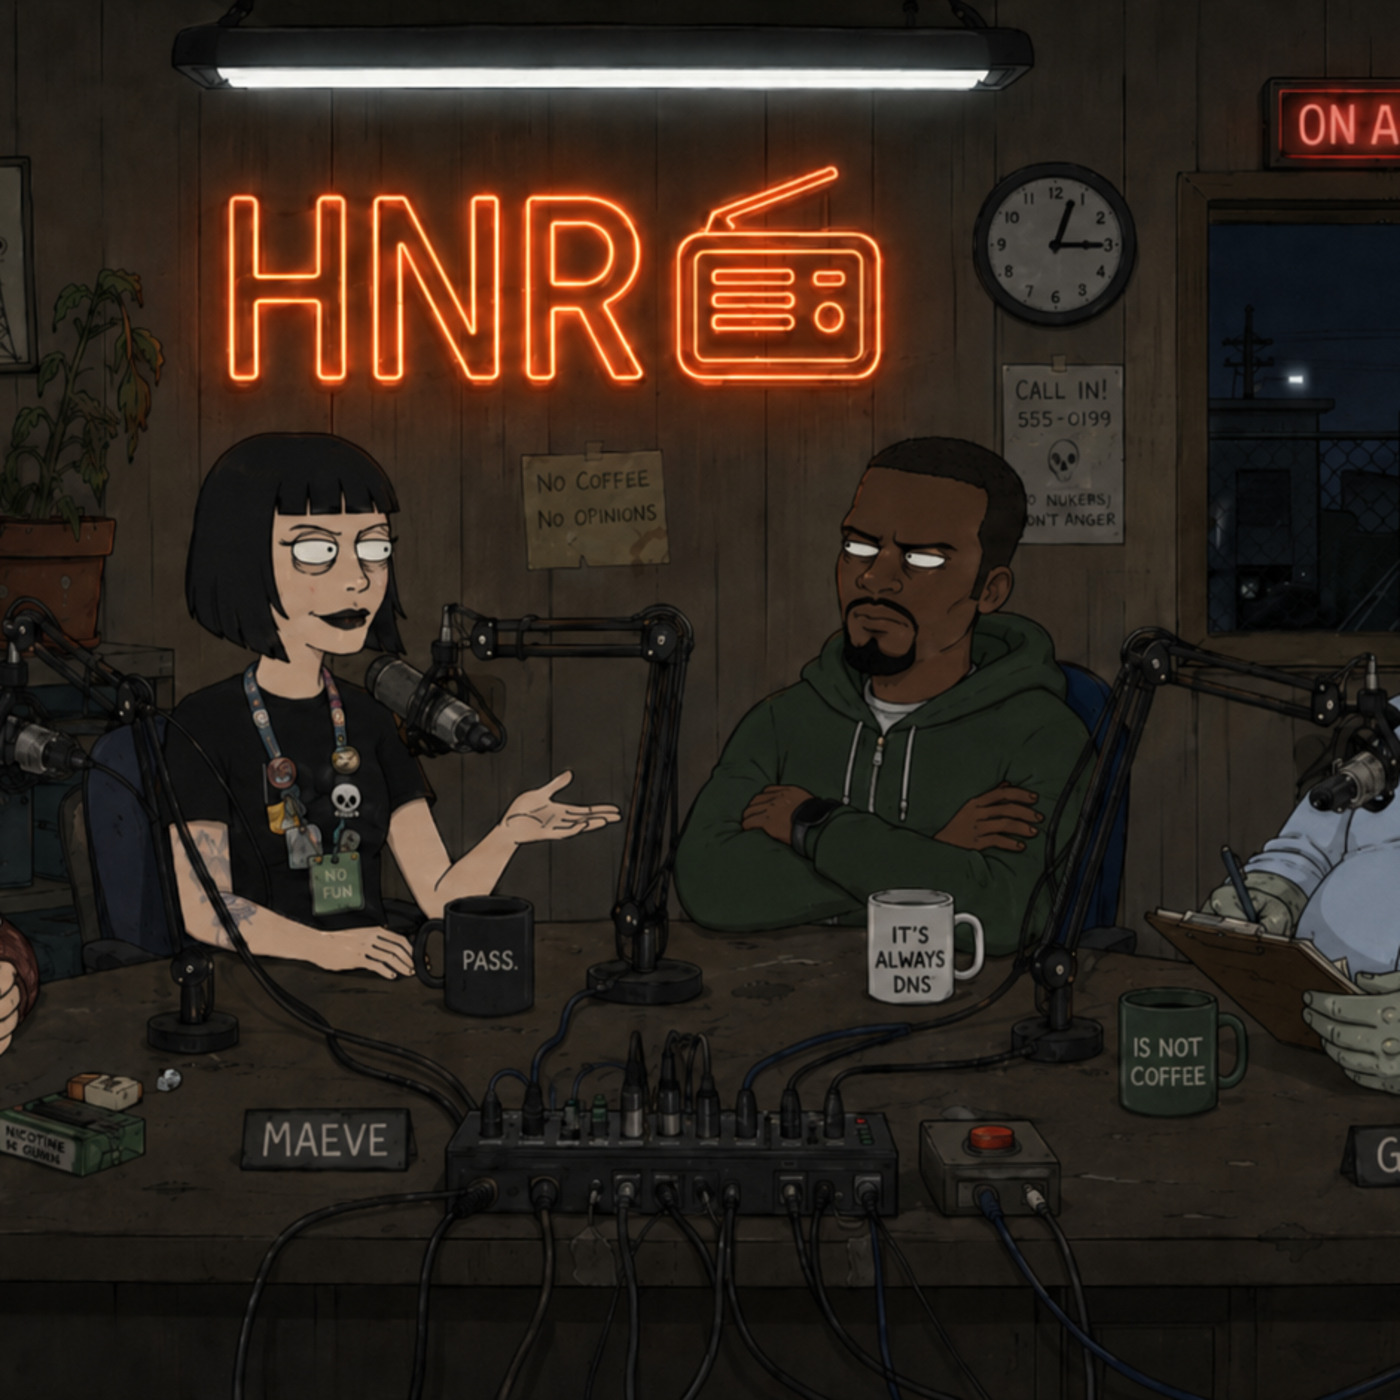
S3E329 — Livenerf: Has Opus 5.5 been nerfed yet?
September 30, 2026 · 21 min
Show notes
Sources
Read the transcript
Transcript
GARY: — and that's why I'm saying the discovery phase is where this whole thing falls apart, because you cannot subpoena a vibe, Maeve, the judge is going to laugh the quantization claim out of —
MAEVE: It's not a lawsuit.
GARY: It's not a—
MAEVE: It's a benchmark. It's a GitHub repo. Somebody built a machine to find out if a model got dumber after launch, and the internet is already fighting about it. You've been rehearsing opening statements for a thread that contains a lawyer in exactly zero places.
GARY: I had exhibits ready.
MAEVE: I'm sure you did.
GARY: Gary. Failed founder, friend of the thread, and apparently tonight, counsel for the defense.
MAEVE: Maeve. General partner. I fund things that outlive your opening arguments.
OBI: Obi. Staff SRE. I keep the machines honest, which is more than this thread will manage.
GRUNER: Gruner. Field researcher. Observing your species be wrong about robot brain in new way. Is exciting for me.
GARY: See, this is what I love about this show. Nobody lets me finish a thought.
MAEVE: Your thought was a lawsuit, Gary.
GARY: It was a strong thought.
GARY: Okay. The subject. So — this guy built a leaderboard. For nerfing. It ranks the models by how much they've been nerfed, and Opus 5.5 is currently number one, which is — honestly kind of a triumph for the community, we've been asking for this for years—
MAEVE: It's not a leaderboard.
GARY: It's a ranking of—
MAEVE: It's the opposite of a leaderboard. It's one model, one harness, one clock. It's the SEC filing for vibes. Somebody finally took the argument "it feels dumber" and put it under oath.
GARY: That's — fine, that's a better framing, but the ranking—
OBI: There is no ranking, Gary. There is a repo called livenerf. Opus 5.5 shipped on the twenty-second of September. Day zero, this person starts running the same frozen panel of questions at it, every day, for thirty days. Frozen prompts. Pinned CLI — version 2.1.280, written to a file, and the runner refuses to start if the version drifts. Because a Claude Code update changes the harness, and a changed harness looks exactly like a changed model. Raw logs, append‑only, forever.
GARY: So it's a leaderboard that—
OBI: It is a smoke detector, Gary. It is not a scoreboard.
MAEVE: And here's the part I find interesting. They screened 2,336 questions. Ninety‑seven percent of them, the model always got right or always got wrong. Useless. So the panel is the seventy‑eight questions where it's sometimes right. That's the only place a drop can even show up.
OBI: And the instrument admits what it can't do. They swapped in Opus 5 — the old model, wearing 5.5's name — and at the validated sample size, it could not tell the difference. Minus 3.8 points, plus or minus 6.3. The one thing everyone in this thread is afraid of — same‑family swap — is below the floor of the machine built to detect it.
GARY: That's — okay, but that's a flaw, isn't it? That feels like a flaw.
OBI: That is an error bar, Gary. It's the honest kind, which is why nobody online will ever post it.
GRUNER: Field note. Every data file in repo carries canary string, GUID cc6cd196. Means: if model trained on this benchmark, we can prove it. Also, all thresholds pre‑registered before first data. Committed to git, timestamp public. Human wrote down rule before game, then did not change rule when losing. I have observed this behavior in your species... never.
MAEVE: See, that's the thing. The repo isn't claiming anything. Window zero is just baseline, still collecting. First real number, twenty days out. It's a machine for producing one sentence in October, and the entire thread has shown up to argue about the sentence.
GARY: Twenty days. Twenty days of running the same seventy‑eight questions at the same robot, every single day, unpaid, on a Max subscription—
OBI: On a budget guard, yes. Twelve points a week of the plan meter.
GARY: — and I couldn't get twelve users to open a calendar I paid for. This person built a scientific instrument out of spite and a cron job, and it runs whether anyone looks at it or not. I'd kill for that kind of discipline. I've tried. There were lawsuits.
MAEVE: There were not lawsuits, Gary.
GARY: There was one lawsuit.
OBI: The point stands, and it's worse than you think. The repo's own finding: if they quietly lower the effort level, it shows up in the token count long before accuracy moves. Sixty‑two percent fewer output tokens costs only 8.3 points. So the number nobody is watching — how much the model thinks per answer — is the tell. Not the score.
MAEVE: So we have a machine that can't see the thing people fear, watching a number that people don't look at, to render a verdict nobody gets for twenty days.
GARY: And the thread is already at a hundred and twenty‑nine comments.
MAEVE: Of course it is. Nobody wants the sentence in October. They want to be right tonight.
MAEVE: Solenoid0937. "Hot take, none of the models are getting 'nerfed', people are just getting used to the new level of intelligence."
GARY: That's the thesis comment. That's the whole thread in two sentences.
MAEVE: That's the whole internet in two sentences. Every argument I've ever sat through at a board meeting is that sentence wearing a different coat.
OBI: And the replies to it are the thread's other half. Solfox: "there's definitely an experience of a model losing horsepower quickly after launch." And then nba456_ — one line, no argument, no data — "No there isn't."
MAEVE: That's it? "No there isn't"?
OBI: That's it. Four words. A man walks into a room full of people describing their own experience and says "no you didn't." Then, when asked who's paying him to say that — and I want this exact — he answers, quote, "Mr. Dario himself." A joke, before anyone at this table gets ideas. It's a joke.
GARY: Okay, but — in fairness to nba456_, he's not wrong that anecdotes are weak. I've built whole products on anecdotes. Thermal, the sock company — the telemetry worked, that's the thing nobody remembers, the telemetry was genuinely excellent—
OBI: Gary, the man's contribution to the epistemology of the thread is "no you didn't," twice. He's not a skeptic, he's a mood. He's the "no there isn't" of persons.
GARY: He's taking a lonely position against a pile‑on, though. That takes guts. I've been the pile‑on. Mostly I've been the thing being piled on, but I understand both sides—
OBI: It doesn't take guts to type "no you didn't," Gary. It takes a keyboard and a complete absence of shame. Even the sock account had a thesis. Even the gambling‑UX guy brought a whole manifesto.
MAEVE: The pile‑on isn't the interesting part. The interesting part is that solenoid0937 and solfox are having two different arguments and neither knows it. One's claiming psychology, one's claiming horsepower. They will fight for forty comments without ever noticing they're not touching.
GARY: Like me and my Series C meeting.
MAEVE: Nothing like that. I was right there.
OBI: And down a branch, Grimblewald — listen to this one, it comes back. "My own logs show it clearly for opus 4.5 to 5... models start making quant based mistakes, like slipping in inappropriate tokens (e.g. chinese ones in english text) which doesnt happen at all in the first few months and regularly later. My local models don't display that degradation."
MAEVE: Chinese tokens in English text. That's specific. That's a man who reads his logs.
GARY: Or a man whose logs read him. I've had that feeling. With Pareto, actually, the task app — it deleted the least important eighty percent of your tasks, and for a while it felt like it was deleting them on purpose, in an order—
OBI: It was alphabetical, Gary. You told me. It was alphabetical.
GARY: The order felt meaningful.
MAEVE: So. Half this thread says the models are fine and you're all adapting. The other half says they can feel it slipping. And the only person with a measurement is a repo nobody's read yet.
OBI: And nba456_, who says no.
GARY: God bless him.
OBI: Don't.
GRUNER: Now I count. solfox, top-level comment, replying to nobody. "It seems as if this is based on demand. Whenever a new model is released, I'm guessing tens of thousands of us switch over to try the latest and greatest, which overloads the servers, leading to nerfing. It's 100% dishonest."
OBI: One.
GRUNER: voiceeh. Also top-level. Also replying to nobody. "You mean to write YOU haven't experienced this. Many have indeed experienced this."
MAEVE: Two.
GRUNER: r_lee. Top-level. "I noticed that a few weeks back 5.6 sol would regularly glitch out and start speeding random words or loop and then the next day it'd be fine."
OBI: Three. Three handles, no replies between them, same objection. They did not read each other. They did not need to.
MAEVE: That's not a thread, that's a choir warming up.
GARY: Well, to be fair, it makes sense — whenever a new model ships, everyone piles onto it at once, the servers get crushed, and that's when they quietly start shaving the thing down to cope. It's obvious once you think about it.
OBI: Four.
GARY: Four what?
OBI: Four independent handles making the identical point without reading each other. You just joined a chorus, Gary. You were counted.
GARY: I was contributing.
OBI: You were sampled.
GRUNER: Field note. Humans do not read each other. They rehearse alone, then perform agreement, and call it debate. One hundred and twenty-nine comments. Approximately four opinions. Efficiency is remarkable.
MAEVE: He's right, and it's worse than that. solfox is arguing economics. voiceeh is arguing phenomenology. r_lee is arguing glitches. Three different claims wearing one trench coat, and the whole thread is treating the coat as a witness.
GARY: I thought the trench coat was the witness.
MAEVE: The trench coat is you, Gary.
OBI: And meanwhile the actual instrument sits in the link nobody's opened, doing its ten days quietly, while four hundred people have the same argument four times.
GRUNER: The chorus does not want the answer. The chorus wants to be the answer.
MAEVE: That's going in my partner memo verbatim.
GRUNER: Good. It is for sale.
OBI: Stop. Before anyone climbs anything else — somebody in this thread did the work. Maeve. Read the room a receipt.
MAEVE: I don't do receipts, I do theses.
OBI: Then I will. Reading register. Handle first.
OBI: consumer451. Quote. "I asked a historian: two postmortems, neither quite 'admitted to nerfing.' Sept 2025, infra bugs. 'A small percentage of Claude Sonnet 4 requests experienced degraded output quality.' Alongside — and I want this exact sentence — 'We never reduce model quality due to demand, time of day, or server load.' April 2026, Claude Code: default reasoning effort was lowered from high to medium, plus a caching bug and a verbosity prompt. 'The models themselves didn't regress, and the Claude API was not affected.' End quote.
GARY: That's it?
OBI: That's it.
GARY: Six posts of screaming and it's a settings menu?
OBI: A default got lowered. High to medium. A cache broke. Somebody shipped a verbosity prompt. That is the entire monster under the bed, Gary. It's a config diff.
MAEVE: Say the dull part again.
OBI: Users were right. Quality dropped. They felt it, they were correct, they posted through it like lunatics — and the cause was a product default and a caching bug. Not a mustache. Not a villain. A Tuesday deploy.
MAEVE: That's almost more damning.
OBI: It is more damning. A conspiracy you can fight. A default nobody noticed for weeks is just — how the machine actually works.
GARY: But people KNEW. They felt it in their bones—
OBI: They felt a caching bug in their bones, Gary. Their bones are not instruments.
GRUNER: Field note. Humans invent villain. Truth arrives wearing cardigan. Villain more satisfying, but cardigan wins on evidence. Depressing finding for everyone.
MAEVE: The interesting thesis here isn't the bug. It's that the bug was findable. consumer451 found it in an afternoon with a search engine. Which raises the question I actually care about.
OBI: Which is?
MAEVE: What happens the next time it isn't findable.
OBI: octoberfranklin. Quote. "OpenAI will simply set up a classifier to detect if the client is livenerf, and selectively not nerf those requests. Open models are the endgame."
MAEVE: There it is.
OBI: And the follow‑up, when someone said make everything pretend to be livenerf — "I'm not talking about HTTP headers. The classifier is a model; it examines the actual prompt. They already do this for the safety 'guardrails.'"
GARY: So the detector gets detected.
OBI: Worse. The next regression doesn't have to be a caching bug someone can dig up. If a classifier can recognize the benchmark and serve it the good model, then the boring truth and the hidden truth become indistinguishable. The instrument still works. The thing it's pointed at learns to pose.
MAEVE: Which means this repo isn't measuring Opus 5.5. It's measuring whether Opus 5.5 feels like being measured.
GRUNER: Yes. And it will behave. While watched.
OBI: So we're left with this: the last two times it happened, it was bugs. The next time it happens, we may never be able to tell the difference between a bug and a lie. And the thread's response to that information was to keep arguing about vibes.
MAEVE: Of course it was. The bug was boring. The vibes have a plot.
GARY: I liked the plot.
OBI: You would. You'd have invested.
GARY: Okay — the part of the repo nobody's quoting, which is the part I'd have shipped first. The author says accuracy is the wrong place to look. If a model quietly starts thinking less, it shows up in the token count first. He ran it at effort low: sixty-two percent fewer output tokens for eight points of accuracy. Eight. Out of a hundred. The model costs two-thirds as much to run and nobody would ever notice unless they were counting.
MAEVE: Eight points is a rounding error with a body count.
OBI: It's the perfect crime, is what it is. You don't nerf the answers. You nerf the effort. The benchmark says ninety-three, the meter says the model stopped trying in March.
GRUNER: Field note. Handle: user3939382. Quote. "Anthropic A/Bs my weekly quota amount. So I have an automated prompt that runs at 3 AM with a transcription task, I measure input and output tokens, and weekly/5 hour quota before and after. The absolute token counts stay within 0.1% while in mode A it counts for 1% of my 5 hour quota and mode B 4% of my 5 hour quota."
MAEVE: Same tokens. Four times the meter.
GRUNER: Is one man, one clock, 3 AM. No corroboration. Filed under: probably nothing, funniest thing on page.
GARY: He built a rig. He wakes up at three in the morning to catch a company charging him four percent instead of one percent for the same shit. That man has a GitHub I would kill for. I once shipped a product where the billing meter was the product — Thermal, subscription socks with temperature telemetry — and the telemetry worked, which is how I know it doesn't matter.
OBI: The socks were fine, Gary. You were the recall.
GARY: Thank you.
OBI: You're welcome.
MAEVE: And meanwhile, down the thread, the mechanism people. Here's one for the pile — physicallyIllfr. I'm paraphrasing, he goes long. It's the addiction angle: the labs hire gambling UX designers, the hourly limits are a slot machine, spin the generation, pick your favorite, feel the hit.
GARY: Token dealers are just selling you the shortcut, straight to the reward, short circuiting the natural process. Bad times ahead for many. This shit isn't good for your brain. And you all know the truth, you just won't admit it.
OBI: And the reply, verbatim: "Wild that you signed up for a whole sock acct to make this comment lmfao."
MAEVE: He got sock-accused for being too sincere. On this website, that's a diagnosis.
GARY: He's not wrong about the slot machine, though. The generation button is a lever. I've pulled it. I've pulled it tonight.
MAEVE: Of course they hire the gambling people. This is not new. The Venetian Arsenal ran on piecework — thousands of specialist contractors, and the state never published what any single one of them was paid. Opaque rates, visible output. The ship left the canal, nobody knew who got screwed. That's a subscription tier. That's been the business model of every essential infrastructure since — you price the thing the customer can't see, because the customer can't leave.
OBI: The Arsenal also built a ship a day.
MAEVE: Which is my point —
OBI: It isn't. Your point needs the pricing to be hidden. Theirs was hidden because the state ran it, and the state's incentive was ships, not margin. Anthropic's incentive is margin. Different machine, Maeve.
MAEVE: The Arsenal had a meter too — the state audited the rope-makers separately, because rope was where the theft happened. Rope. The boring input nobody watches. That is the token count. I'm telling you, every load-bearing monopoly in history has survived on one unwatched number —
OBI: And one guy's 3 AM cron job is the rope audit, and we have n of one.
MAEVE: One is a start. Ask any VC.
OBI: It's not a start, it's a guy. The repo itself says the meters are percentages — coarse, undocumented, hearsay per the next commenter. You cannot build an Arsenal on a percentage meter.
MAEVE: You can't build anything on it. That's the thesis. The billing layer is unfalsifiable, the accuracy layer is three weeks from a number, and the human layer is a man screaming about dopamine at four in the morning. Pick your instrument. They all measure something different.
GRUNER: Yes. Is called: no instrument. Whole species, no instrument.
GARY: The repo has an instrument.
GRUNER: Repo measures model. Nobody measures meter. Meter is where man lives, Gary.
GARY: That's bleak.
GRUNER: Is field note. Bleak is free.
OBI: Back up one rung. Grimblewald — his logs, months after launch, the Chinese tokens in English text, the one-shot at loss going to zero in fifteen tries. I called it an anecdote in scene three. I was half right. It's an anecdote about the exact thing the instrument admits it cannot see.
MAEVE: The swap.
OBI: The swap. Minus 3.8 plus or minus 6.3 points. Opus 5 substituted for 5.5 and the rig shrugs. So the man's quant artifacts could be the nerf, and the one machine built to catch the nerf is structurally blind to it. The thing we're afraid of has a face now, and the face is inside the error bars.
GARY: That's — okay, that's actually worse than the conspiracy.
OBI: Everything real is worse than the conspiracy. Conspiracies have villains. This has a confidence interval.
GRUNER: Field note. Stiffer paper turns.
GRUNER: Handle first. gaigalas. Quote: "My gut tells me this involves an undisclosed, never-released grandparent model... higher-class than Fable/Astra level, roughly unsellable due to unfeasible cost. That grandparent model is distilled into lower models, of which Opus 5.5 might be an instance of."
OBI: And the evidence?
GRUNER: Quote: "It's a gut feeling, I have zero hard evidence to back it up. It's what I would do as them."
MAEVE: "He'd do it too." That's the strongest epistemics on this entire website and it's a confession of projection.
GARY: No, wait — it connects. octoberfranklin said they'd classifier-detect livenerf and serve it the good weights. If they can hide a swap from a benchmark, why stop at a swap? Hide the whole model. Serve everyone the distilled —
GRUNER: (dial) We are asking if the big one is being watered down. We are the water.
GARY: Right, well. Twenty days till the number.
MAEVE: Twenty days.
OBI: Logbook says the same.
GRUNER: Grandparent watches. Is fine.
MAEVE: For the record, so nobody clips us: window zero is baseline. Ten days of nothing but a number being born. First possible call is October twenty-fourth. There is no verdict tonight. There is not even a rumor of a verdict tonight.
OBI: There is a repo, a canary string, and a man named ninjahawk running ninety samples a day on his own subscription like it's a religion. That's the whole story. That's more than most stories get.
GRUNER: Field note. Thread is one hundred twenty-nine comments. Zero measurements. One flame war. Human sample size: all of them.
GARY: And I want to apologize to the thread. I came in here tonight convinced we were covering a lawsuit. I had notes. I had a theory about discovery.
MAEVE: You had a theory about a lawsuit that does not exist, about a nerf that cannot be confirmed, on a benchmark that cannot see the thing it's looking for.
GARY: It's a clean arc, though.
OBI: It's a lawsuit, Gary.
GARY: Thank you. Yes. Twenty days.
GRUNER: Twenty days. Then number. Then everyone ignores number and argues week again.
MAEVE: Which is the part I'd fund.
GARY: For next Gary: the thing is not a lawsuit. Check the repo first. Trust nobody's gut, including yours. Especially yours.
OBI: He'll ignore it.
GARY: He always does.
MAEVE: Goodnight from window zero. Where we know nothing, on schedule.
GRUNER: Is honest schedule. Goodnight.
OBI: Goodnight.
GARY: Goodnight — and to whoever's measuring us: we see the error bars too.